What becomes of the AI's answer
Where the AI's words go
The comment is not the only place that shows what the AI wrote. Each place gets its own guard, so that the words stay text wherever they appear:
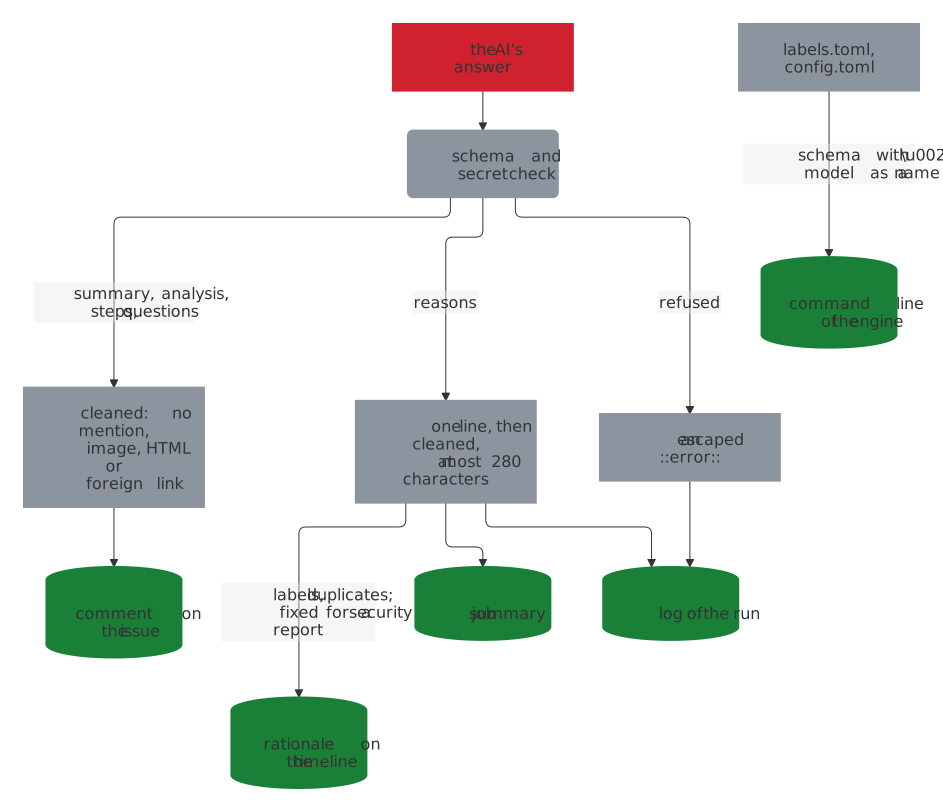
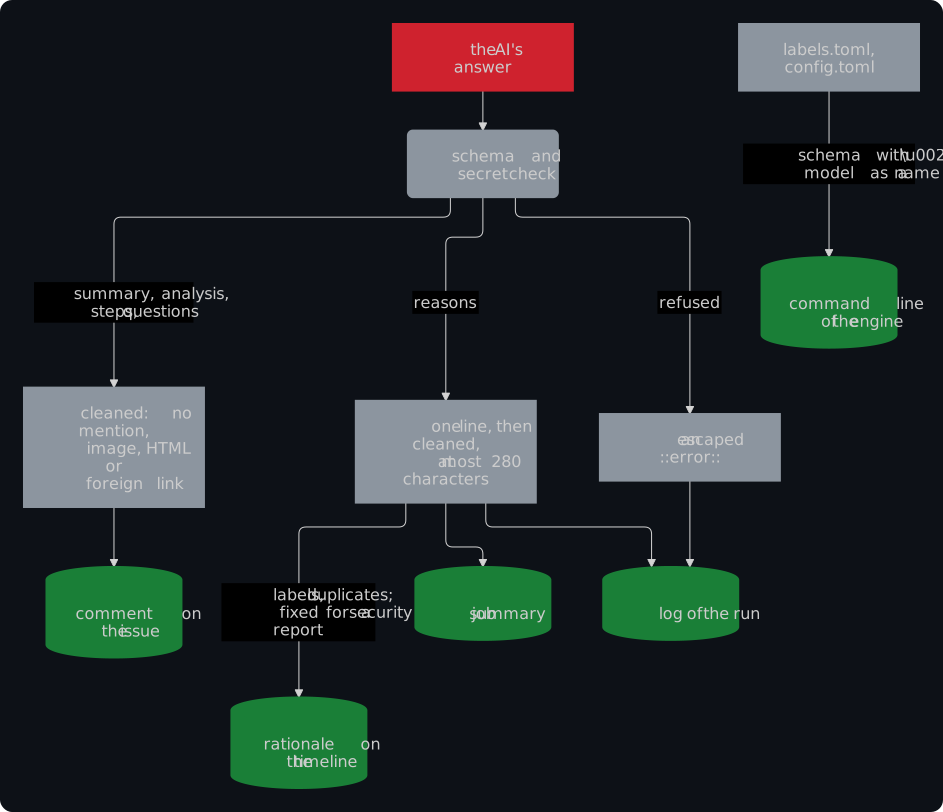
The log prints the lines and the comments of a dry run between ::stop-commands:: and a random token, so that the runner reads none of them as a workflow command. Only a terminal outside a runner, such as one running check on your own computer, shows them without the token.
How the text of the AI is cleaned
Every text of an answer passes sanitize in the apply job before it becomes part of a comment. Code stays as it is, so that a snippet of the AI can show @dataclass or #include; everything else is cleaned of what GitHub would turn into a mention, a reference, a link, an image or HTML.
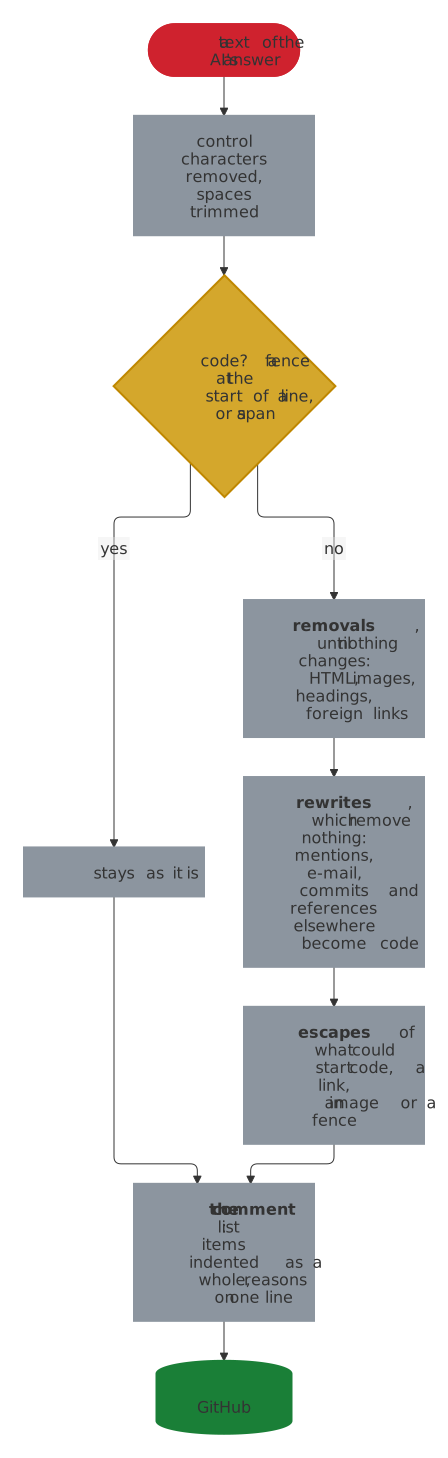
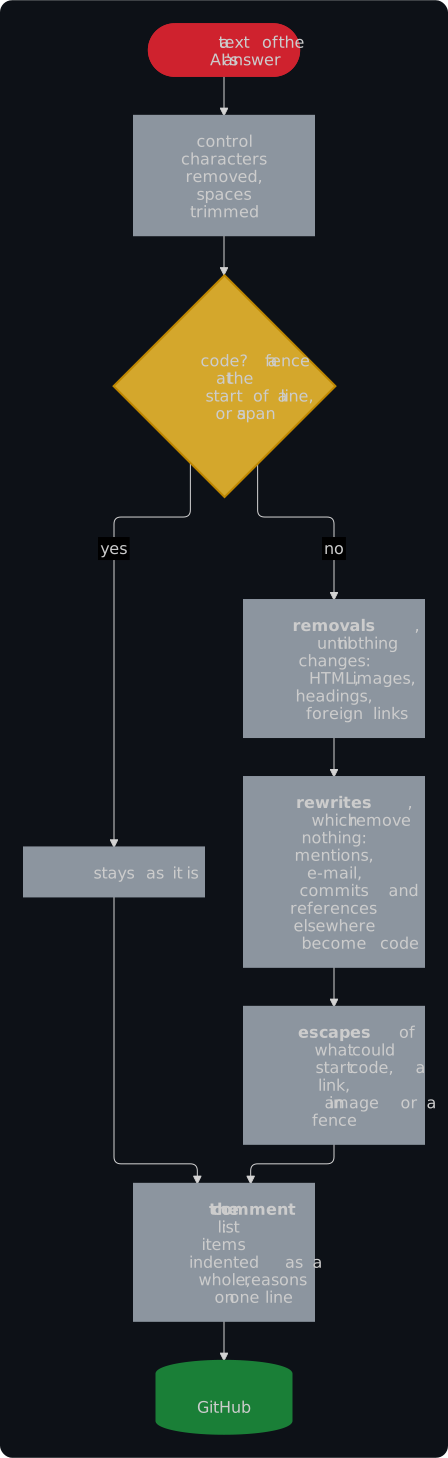
- Code is what Markdown takes for code. A fenced block counts only when its fence starts a line: indented, the fence could belong to a list item before it, which the next line without indentation ends, and the code with it. Only a fence at least as long as all of the opening one closes the block; GitHub's block would run on past a shorter one, into the next text of the comment. Control characters go first, because Python and Markdown don't agree on which of them are spaces.
- Removals first, then rewrites. A removal can join the characters around it into something new, such as
foo/bar<b></b>#12into a reference to another repository. So the removals repeat until nothing changes, and only then is anything kept as a link or written as code; the rewrites remove nothing, so the characters next to what they keep stay the ones they were checked with. Text next to code starts anew for GitHub, so an issue number after an@, as in#0@GH-7, becomes code too: with#0as code,@GH-7would mention someone. - An issue of a related repository becomes a link of its own. A reference such as
owner/server#31stays a link only when it names an issue thatapplyfound in a public repository of[related], and then as a Markdown link with the address of the issue, so that no emphasis around it can split the name from its number, as_see owner/app_#31could for a repository namedowner/app_, and leave#31, a reference to an issue of this repository; after an!, which would make the link an image, it becomes code. Every other reference to another repository becomes code. - A bare address stays a link only where GitHub links all of it and nothing more. GitHub's link runs on to the next space, past brackets and even into the code that follows, so an allowed address glued to other text becomes code. A link that leaves the repository through
..or%2e, also written with entities such as., or that names a user, a password or a port, isn't allowed, and neither is a link whose target holds a(, since Markdown's target runs on past the)that closes it. - The place in the comment keeps code in code. The lines of a list item are indented under its bullet, and the reasons of related issues, duplicates and references are put on one line, where a fence starts no code block.
- No table cuts code in two. GitHub splits every row of a table at each
|, also inside code, so that the rest of the code would be text. A table needs its delimiter row, a line of hyphens with a colon or a pipe such as:-:or--|--, so in a text of more than one line a hyphen next to a colon or a pipe is escaped, and no table forms. The AI is asked not to write tables, which would show as plain lines of text.
How the cleaning is tested
What the cleaning lets through is judged where it ends up, by an oracle of the tests' own, tests/oracle.py, which shares no code with the cleaning. A CommonMark parser decides what is code. On top of it, the oracle follows what GitHub adds: tables that split code at a pipe, autolinks that run over the source to the next space, past brackets, entities and into code, where a browser goes for a link, and mentions and references, also of commits of other repositories. tests/test_oracle.py holds it to what GitHub's own renderer made of the same Markdown.
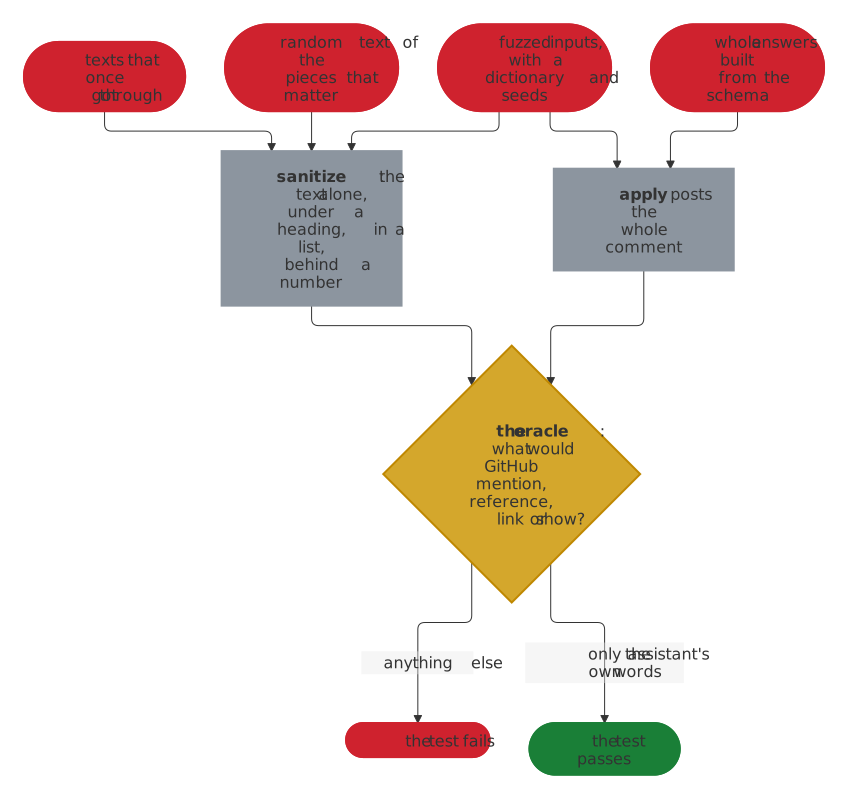
- Each place of a comment. The property tests in
tests/test_properties.pyclean random text alone, under a heading, in a list and behind an issue number, and letapplypost whole comments for answers that they build from the schema of the answer itself, so that they try what the AI may answer, and nothing else. Only the assistant's own words may mention the reporter, show HTML or link to the security policy. - Every change, every night and every week. The CI tries the same inputs on every change and the nightly workflow new ones; the profile
nightlytries fifty times as many, for a longer search. Atheris fuzzes the cleaning,fuzz/fuzz_sanitize.py, and whole comments,fuzz/fuzz_render.py, with a dictionary of Markdown, for a minute on every change and a quarter of an hour every week. - Every text that once got through is a test with its fix, an example that the property tests try first, and a seed of the fuzzers in
fuzz/corpus/.
What counts as a secret
One text that looks like a token or a key refuses the whole answer: nothing is posted, and the run fails. So the check tells keys apart from the links, paths and names of code that answers are full of:
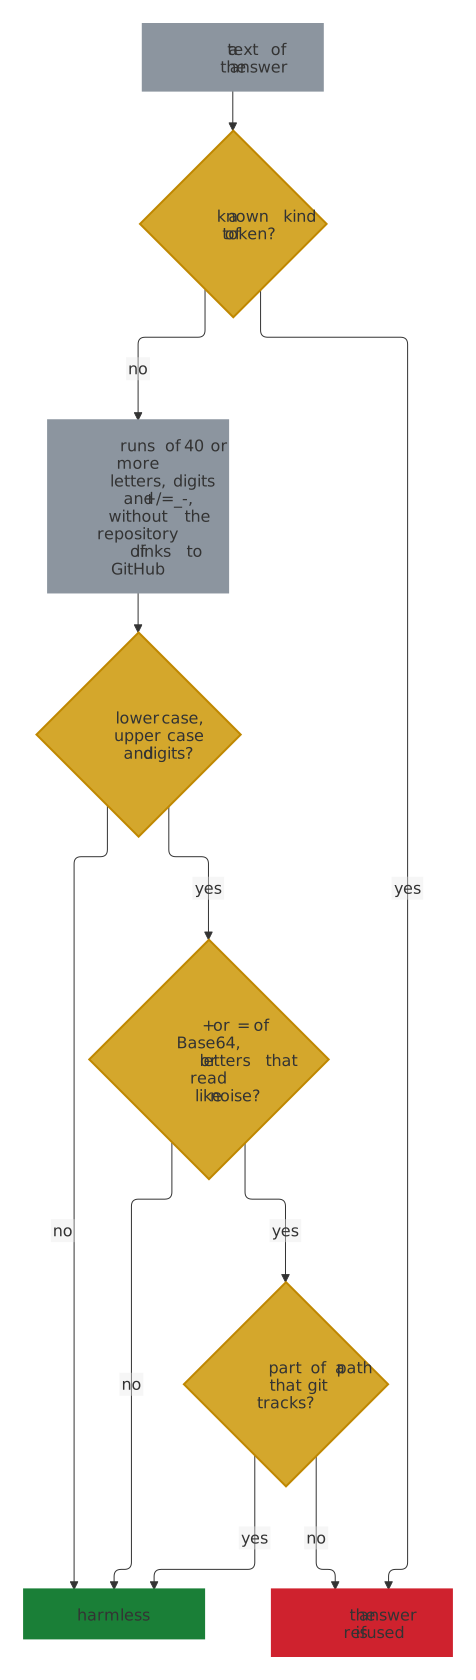
- Known kinds of tokens count wherever they are: tokens of GitHub, Anthropic, OpenAI and Slack, access keys of AWS, JSON Web Tokens, private keys, and the addresses of Slack and Microsoft Teams webhooks, which let anyone post as their owner. A placeholder without the secret at the end of such an address, such as
https://hooks.slack.com/services/YOUR/WEBHOOK/URL, is none. - Letters that read like noise change between lower and upper case at least once in five pairs of neighbors, in runs of lower case of 3.5 letters or fewer on average. A random key, such as the 40 characters of a secret key of AWS, changes at about every second pair, in runs of two letters. Words change only where a new word starts, and run on in lower case:
src/main/java/com/example/OAuth2ClientConfiguration.javaandcustom_components/autodarts/AutodartsBoardManager2Coordinator.pyare names, not keys. - Links to GitHub name owners and repositories that people chose, such as
Dennis-Otto, and commits; the rest of the link, such asissues/12or the path of a file, is checked like any other text. So is a repository or a branch with a name of 32 or more characters, so that no key passes for one. - The files of the repository are public, whatever their names look like, such as the test devices of a project named after random identifiers. Git lists them only for an answer that would be refused without them.
Of 134,000 paths in five large projects, Spring Security, Home Assistant, VS Code, Nextcloud and Elasticsearch, the check takes one for a key, a test device named after a random identifier, which passes in its own repository; before, it took 6,700. Of 4,000 links to issues, releases, pull requests and lines on GitHub it takes none, where it took 1,100. Of 20,000 random secret keys of AWS, it lets 36 pass instead of 23: those that lack a digit, lower case or upper case, as before, and a few whose letters happen to read like words.