Failures and hard texts
When a call to GitHub fails
Every call goes through gh api, in GitHub._gh. When it fails, the GitHubError carries what GitHub said: the HTTP status from the message of gh, gh: Not Found (HTTP 404), and the types of GraphQL's errors from GitHub's JSON, such as NOT_FOUND. Its methods decide what happens next:
| The error | What happens |
|---|---|
missing(): status 404 or 410, or the type NOT_FOUND |
the thing doesn't exist: no other issue, discussion or release, a commit that no release contains, an issue that was deleted or moved |
rate_limited(): a secondary rate limit |
GitHub refused the call before doing anything, so it runs again after a minute, a write too, up to 3 times; gh never shows the header Retry-After, and a minute is what GitHub asks for without it |
transient(): a status of 500 or more, or a broken connection |
a read runs again after 2, 4 and 8 seconds; a write doesn't, since GitHub may have done it anyway |
| any other, such as the rate limit of the hour | the error goes up to the command |
Only the places that look a thing up catch an error, and only when it is missing(). Every other error stops the command: main prints it as one escaped ::error:: and the summary lists the writes of the run before it, and the write that failed. A run again repeats nothing, because every step checks first what is done:
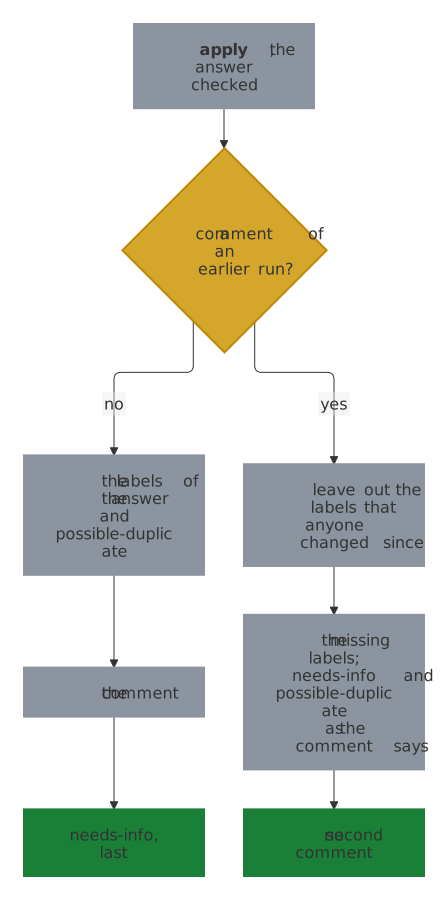
The sweep runs each step and each issue through isolate: a GitHubError becomes a ::warning:: and a line of SweepIncomplete, which main reports with what was done before it fails the run. The steps of the sweep check what an earlier one did: a fixed issue loses needs-info and stale and gets fixed-in-next-release before its notice, so a failed notice never leaves it waiting for an answer, a comment of the release, of the closing of an unanswered issue or of a duplicate isn't posted twice, and an issue closes before its labels are removed, so the next sweep still finds one that GitHub didn't close.
Which release closes a fixed issue. mark_fixed reads the pull requests merged in the last 14 days, MERGE_LOOKBACK, a hundred at a time: GitHub lists them by their last update, which a merge is, so the pages end with the first one that nobody updated within the lookback. A busy repository merges far more than a page in that time. The query gives the state of each issue that a pull request fixes, so a closed one, as most are by then, costs no request of the token's 1,000 an hour; the read of an open issue decides. After its labels and before its notice, mark_issue_fixed asks whether a final release published after the merge already contains the merge commit, as when the run of the merge failed, so that a read of the releases that GitHub fails loses only the notice; then close_issue_released closes the issue at once, unless another fix still waits, and a later sweep never announces a fix that a released comment came after. close_issue_released takes the fixes of an issue from closedByPullRequestsReferences, only those of this repository, merged at most MERGE_LOOKBACK and LABEL_SLACK, an hour, before its last labeled event of fixed-in-next-release (a sweep labels the issue later in its run than the start that its lookback counts from), and not before a released comment that came before its last reopened event: the release closed the issue with that fix, and the reporter reopened it. first_release skips the releases published before the last of them was merged, or before the label without a fix or when someone other than github-actions[bot] set it, and compare proves that a release contains each merge commit. releases reads the newest hundred, as a beta channel publishes a pre-release for each fix.
Reading the text of issues
Anyone can write an issue, and every analysis reads the text of every open issue and of the closed ones that changed last, for the excerpts of the other issues. One text that kept a pattern busy for minutes would stall every analysis until its job timed out. So the time to read a text grows only with its length:
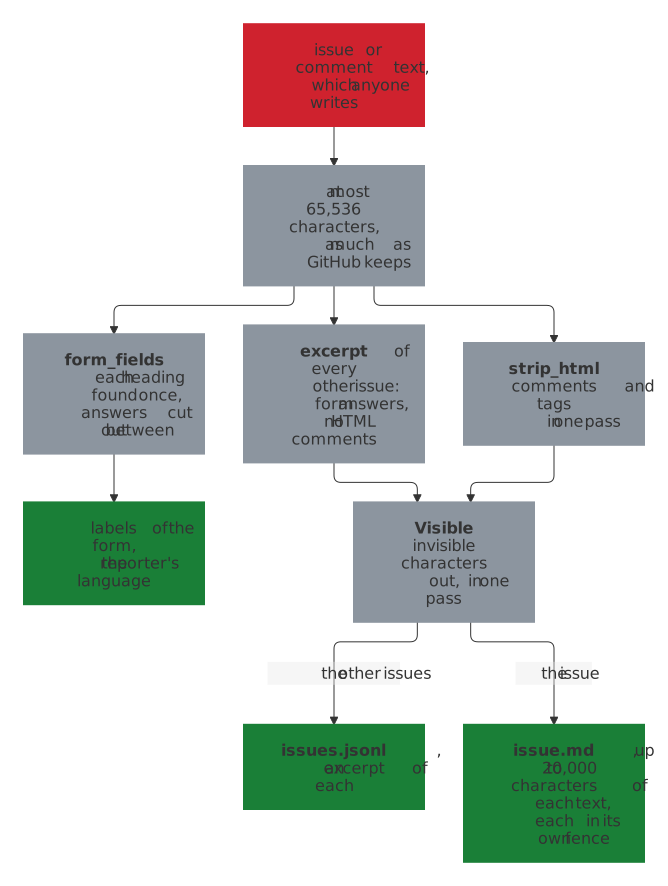
- No pattern backtracks. Each one looks at a character a bounded number of times: a form heading is one line, a tag ends on its line, and when no
>closes a tag on its line, the rest of the line is passed over in one step. - HTML comments go as GitHub hides them. A line that starts with a
<!--that never ends hides the rest of the text, as on GitHub, so instructions hidden that way don't reach the AI either. A<!--without its end within a line stays text, as GitHub shows it. - Each text keeps to its place.
render_issueputs each text in a code fence one backtick longer than its longest run of backticks, under a heading that only the script writes, so no text can pass for another comment, the maintainer or the assistant;Visibletakes out the characters that GitHub shows as nothing before the fence is chosen, so that none can split a run of backticks, and after the HTML, so that none can end an HTML comment that GitHub never ends and show the AI what it hides. The security design shows why. - Tests and fuzzing time it. The tests read texts of 64 KiB that took the earlier patterns up to hours, and compare the results with theirs on ordinary texts;
fuzz/fuzz_issue_text.pyfails when reading a crafted text takes longer than half a second.